
HOW SINGAPORE EDUCATION WORKS · University research data and reproducible joins
Find your next learning step
Before trusting a merged table, prove what the key means, count matches and non-matches, explain the join type and save the audit beside the analysis.
Full chapter index · Practice and checking · Sources and next reading · How Singapore Education Works
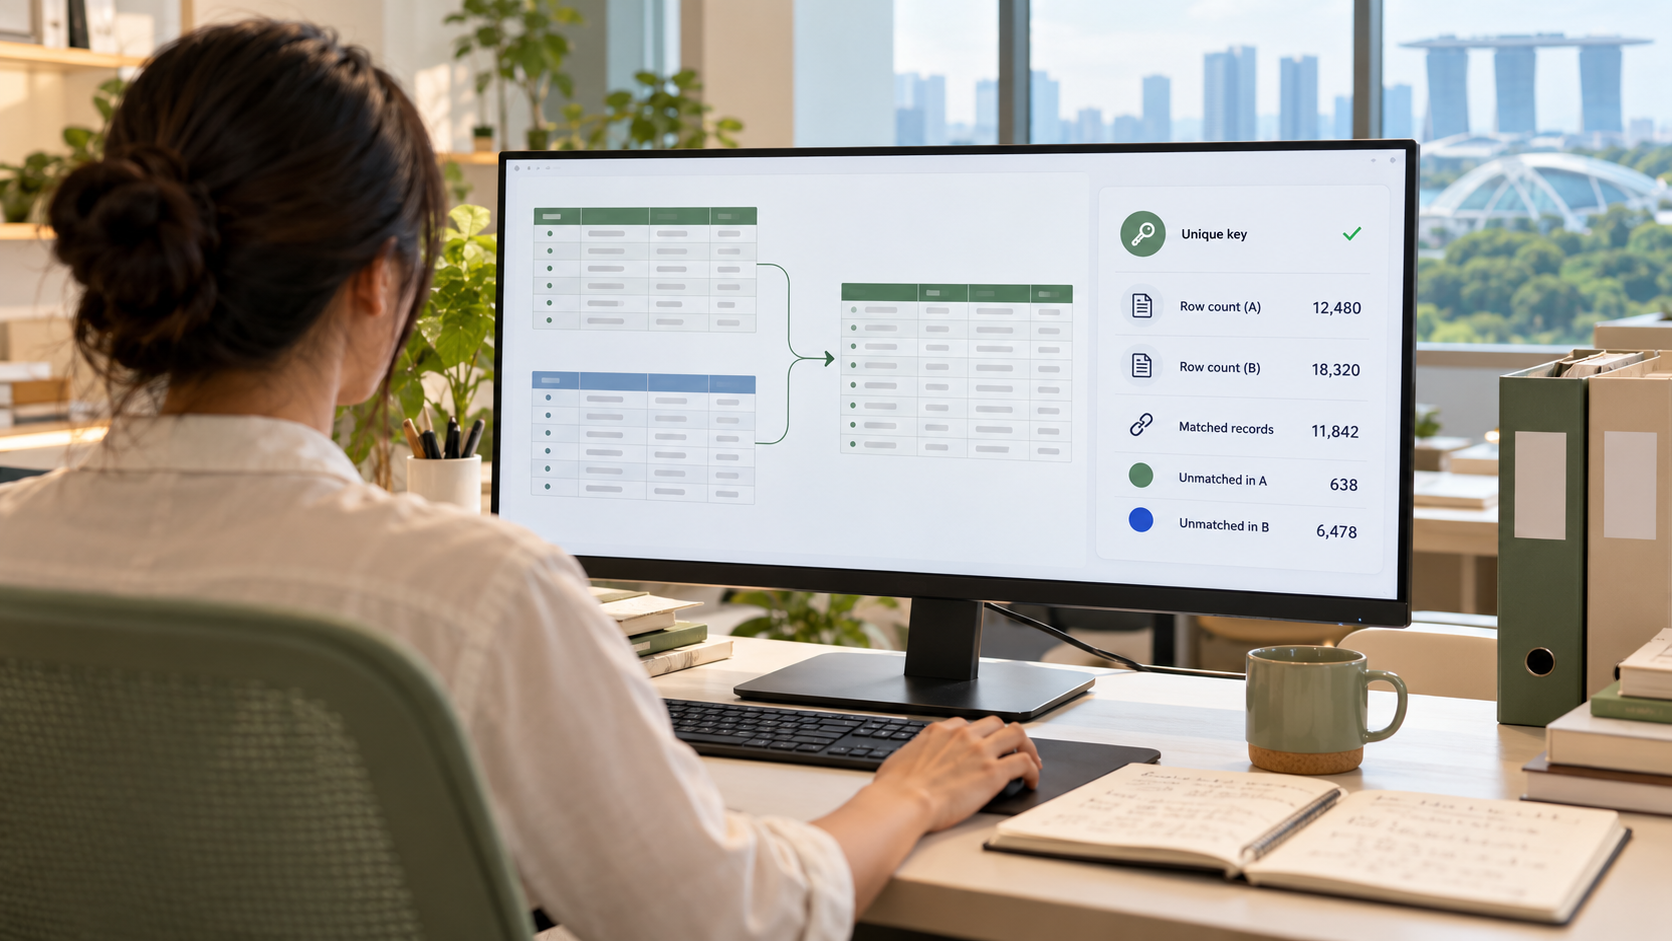
A dataset merge can run without an error and still change the meaning of a study. Duplicate keys can multiply rows; a left join can hide records that exist only in the second file; unmatched codes can turn into missing values. The defence is a small merge audit performed before substantive analysis.
This is a research-workflow teaching guide, not a substitute for a university policy, ethics approval, data-use agreement or disciplinary method. Follow the governing institution and dataset documentation, especially where identifiers or sensitive records are involved.
The choices at a glance
| What you notice | Likely issue | Useful next move |
|---|---|---|
| The merged file has more rows than either input | A supposedly unique key is duplicated in one or both tables | Count key duplicates and inspect many-to-many matches before accepting the join |
| Many new columns contain blanks | Records in the retained table did not match the second table | Produce an unmatched-key table and investigate coding, scope and date |
| Results change when file order changes | Join direction or filtering is controlling which records survive | State the join type and expected population before running it |
Full chapter index
See the structure
Work and diagnose
Repair and practise
Recall, transfer and questions
When two rows are joined, the researcher is claiming they refer to the same unit: the same participant, school, specimen, place or time period. The key is the evidence used to make that claim.
Names are often poor keys because spelling and formatting vary. Even an identifier may change meaning across versions or institutions. Document who created it, its scope and whether it should be unique.
Never expose direct identifiers merely to make a join convenient. Use the authorised data environment and approved linkage method.
| Contract item | Question | Example |
|---|---|---|
| Unit | What does one row represent? | One enrolled student in one term |
| Key | Which fields establish identity? | Pseudonymous student ID plus term |
| Cardinality | One-to-one, one-to-many or many-to-many? | One student to many module records |
| Join type | Which population must survive? | Left join keeps the registered cohort |
| Expected counts | What totals should reconcile? | Cohort, matches, cohort-only, result-only |
Many-to-many joins are not automatically wrong, but they should be intentional. If both files contain repeated keys for different reasons, define the additional fields needed to identify a valid pair.
Treat count expectations as assertions. A result outside the range should stop the workflow for inspection.
Assumptions: cohort file A contains 120 unique student IDs. assessment file B contains 118 unique IDs. After standardising the authorised ID format, 115 IDs occur in both files, five occur only in A and three occur only in B.
A left join from A to B must retain 120 cohort rows: 115 matched plus five A-only rows. A full outer join contains 123 unique IDs: 115 matched, five A-only and three B-only.
Checked arithmetic: 115 + 5 = 120 for A; 115 + 3 = 118 for B; 115 + 5 + 3 = 123 for the union. Any different row count requires an explanation such as duplicate keys or filtering.
The three B-only records are not automatically errors. They may belong to a different cohort, a late registration or a scope mismatch. The audit identifies them for authorised investigation.
Duplicate keys create row multiplication. Formatting mismatches create false non-matches: spaces, leading zeros, case or date formats. Scope mismatches are conceptual: one file may cover all registrants while another covers only those who sat an assessment.
Repair formatting only when the transformation is justified and saved in code. Do not force unmatched records together because names look similar.
Inspect missingness both before and after the join. A blank created by non-match has a different origin from a blank already present in the source.
- Assert key type, allowed missingness and intended uniqueness in each input.
- Run the named join without silently dropping warning information.
- Count matched, left-only and right-only keys; inspect duplicate expansion.
- Reconcile totals with the prewritten contract and investigate exceptions.
- Save code, software environment, input versions and a compact audit table.
Keep an untouched input snapshot or a governed reference to it. The merged file alone cannot explain how a record arrived.
If an authorised correction changes a source key, record the correction route. Do not quietly edit identifiers in the final spreadsheet.
Guided
Merge two tiny teaching tables by a unique key and manually mark matches, left-only and right-only rows.
Shared
Predict counts for a one-to-many join, then compare the program output with the prediction.
Independent
For a real authorised dataset, submit the merge contract, code, audit counts and an exception note that another researcher can rerun.
A week later, rebuild the merge from clean inputs and compare a checksum or reproducible summary of the output. If the audit changes, identify whether the input version, code or environment changed.
Health, economics, ecology and education use different units and governance, but the global logic travels: define identity, state the retained population, expose non-matches and document manipulation.
Changed-context transfer: replace participant IDs with place-and-date keys. Ask whether two measurements at the same station but different dates should ever be joined as one row.
Should unmatched records be deleted?
Not automatically. First explain why they are unmatched and apply the approved inclusion rule transparently.
Is a spreadsheet lookup a merge?
Conceptually yes. It makes the same identity claim, so key checks and non-match counts still matter.
What if keys are duplicated intentionally?
State the intended one-to-many or many-to-many relationship and predict row expansion before joining.
Do matching row counts prove correctness?
No. Wrong pairs can still produce the expected count. Inspect key meaning and sampled matched records within the authorised environment.
Sources and next reading
- NUS Libraries — Research Data Management: Data Formats
- NUS Libraries — ScholarBank Policy and Guidelines
- UK Data Service — Analysing and Integrating Multiple Datasets workshop
- UK Data Service — Documentation glossary
Continue inside eduKateSG
- University data-cleaning decision logs
- University computational notebooks
- University research folder README files