
HOW SINGAPORE EDUCATION WORKS · University reproducibility
Find your next learning step
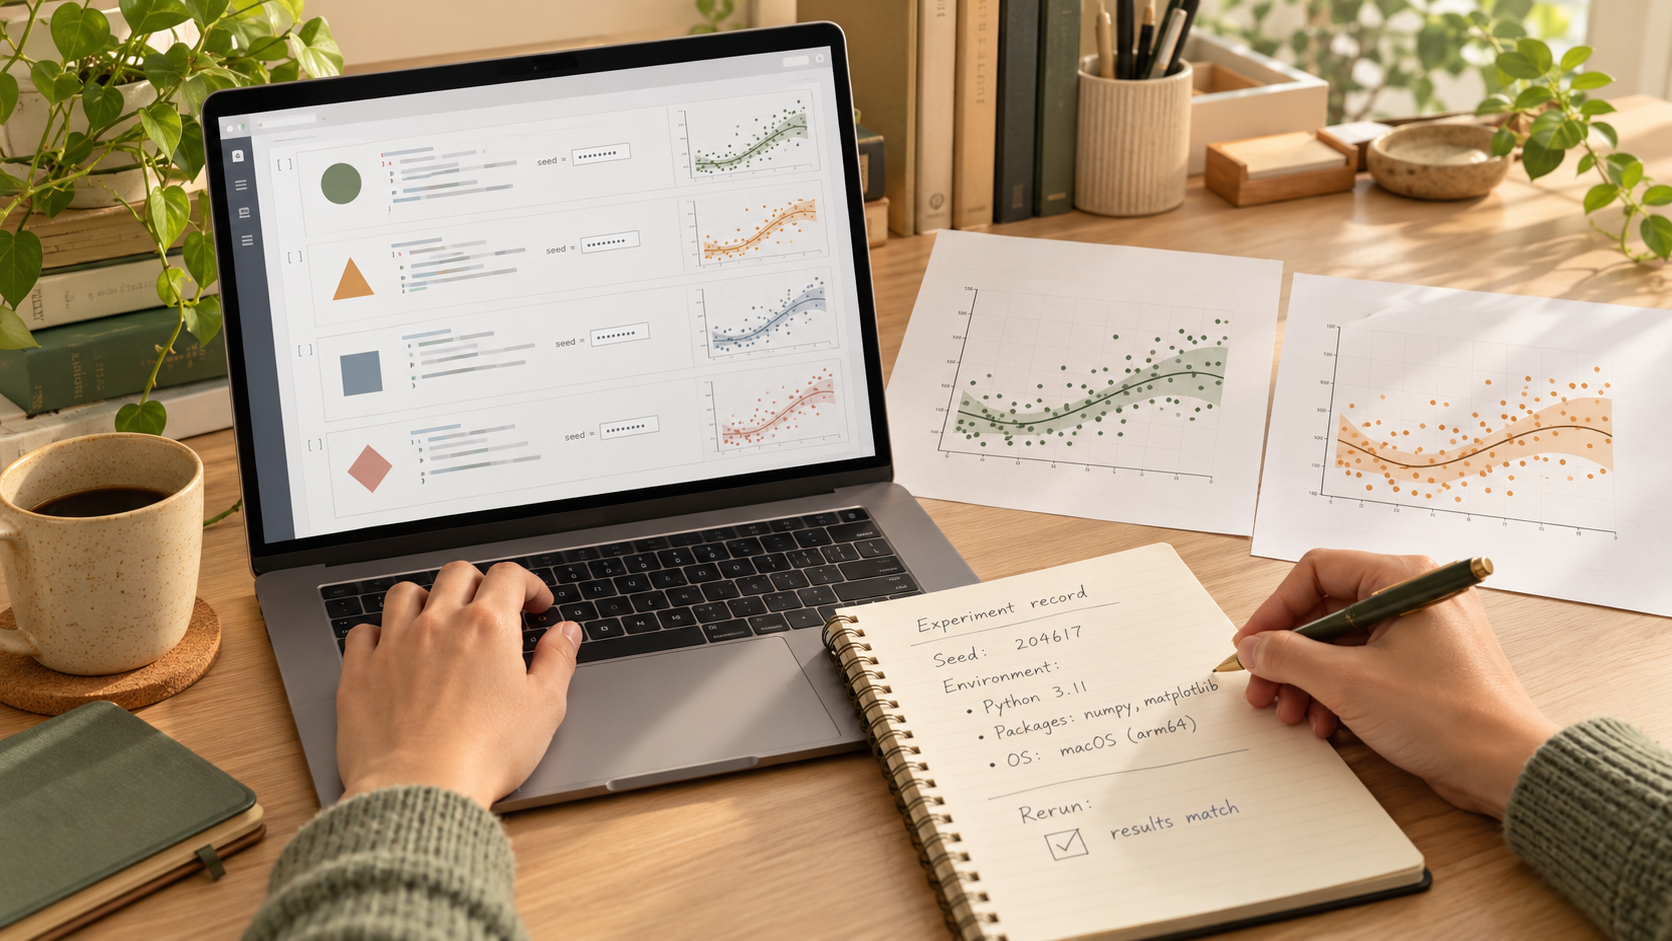
Record the random-number generator, seed and environment; rerun from a clean start; then compare both exact outputs and scientific conclusions. A seed controls one source of variation, not every source.
Full chapter index · Practice and checking · Sources and next reading · How Singapore Education Works
Randomised data splits, simulations, bootstrap samples, parameter initialisation and stochastic optimisation can produce different outputs from the same code. A recorded seed makes a pseudorandom sequence repeatable within defined conditions, but it does not freeze software versions, parallel execution, hardware behaviour or hidden data changes.
This is a reproducibility workflow, not a claim that every result must be bit-for-bit identical. Universities, labs and journals may set additional research-data, software, ethics and security requirements. Use the project’s approved environment and never publish confidential data, credentials or restricted paths in a notebook or repository.
The choices at a glance
| What you notice | Likely issue | Useful next move |
|---|---|---|
| Two reruns use different train/test splits | The split generator or seed was not controlled | Pass an explicit random-state object or seed and record it |
| The seed is fixed but model scores still move slightly | Another nondeterministic layer remains | Check parallelism, hardware, libraries and operation settings |
| One seed produces a strong result that disappears later | The conclusion depends on a lucky draw | Report a distribution across justified seeds, not one attractive run |
Full chapter index
See the structure
Work and diagnose
Repair and practise
Recall, transfer and questions
A pseudorandom number generator produces a sequence from an internal state. Initialising it from the same seed can reproduce the sequence when the generator and relevant software behaviour are the same. The seed is therefore an input to the analysis.
The seed does not make the method non-random. It makes one realisation traceable. Research questions about uncertainty often require many seeds or many resamples; research questions about debugging may require one repeated seed.
Prefer the explicit random generator recommended by the library rather than relying on a global setting hidden elsewhere. Record where randomness enters the pipeline.
List every stochastic step: sampling, data split, augmentation, initialisation, shuffling, optimisation and evaluation. For each, record the library, generator API, seed strategy and output that should be compared.
| Layer | Record | Check |
|---|---|---|
| Data | Input identifier and split indices | Same rows and same order? |
| Randomness | Generator, seed or SeedSequence | Same stream at the intended step? |
| Software | Language, library and lockfile versions | Same implementation path? |
| Execution | CPU/GPU, threads and deterministic flags | Known nondeterministic operations? |
| Result | Metric, tolerance and artefact hash | Exact match or scientifically equivalent? |
If separate steps need independent randomness, derive child streams deliberately rather than reusing one mutable generator accidentally. The exact mechanism depends on the library.
Assumptions: a project has 1,000 labelled records. It uses an 80/20 train/test split with random_state 20261023 and a stochastic classifier with random_state 31415. The locked environment and input file hash are recorded. Run A reports accuracy 0.842 and stores the 200 test-row identifiers.
From a clean process, Run B restores the same environment, verifies the input hash, applies the same split seed and checks the test identifiers before fitting with the model seed. It also reports 0.842. Run C keeps the split but changes the model seed to 27182 and reports 0.839.
Checked answer: Runs A and B reproduce the defined seeded pipeline. Run C tests model-seed sensitivity while holding the evaluation set fixed; the absolute score change is 0.003. That difference is evidence to analyse, not permission to select the higher run. The research conclusion must reflect the planned analysis across seeds and uncertainty.
Exact repeatability asks whether the same inputs and conditions recreate the same bits or values. Computational reproducibility may accept a stated numeric tolerance. Robustness asks whether the substantive conclusion survives reasonable changes in seed, sample or model settings.
Define the comparison before rerunning. A file hash should match exactly; a floating-point metric may use a justified tolerance; a chart may need both data and visual checks. Avoid deciding the threshold after seeing the difference.
A conclusion that holds across a planned range of seeds is stronger than one chosen from many unreported attempts. Keep unsuccessful or ordinary runs in the record.
First verify input bytes and row order. Next verify that every stochastic component received the intended generator or seed. Then compare package versions, compiler or accelerator libraries, thread counts and deterministic-operation settings.
Run the smallest failing component repeatedly. If data splitting changes, do not debug the model yet. If the split is stable but training differs, isolate initialisation, batching and parallel operations.
Document what remains nondeterministic and why. Hiding a small unresolved variation is worse than reporting its measured range and the conditions under which it appears.
Guided rerun
- Restart the process and load inputs from named paths.
- Set explicit generators at every stochastic step.
- Compare stored indices, metrics and artefacts.
Sensitivity run
- Change one seed according to a written plan.
- Keep the evaluation definition fixed where appropriate.
- Summarise the distribution, not only the maximum.
Independent restoration
A colleague uses the README, locked environment, seed register and data instructions on a clean machine or approved workspace, then records matches and deviations.
A week later, rebuild the randomness register from the repository without opening a private notebook. Missing seeds or undocumented global state should become visible during this delayed handover.
International research teams may use different operating systems, processors and compute clusters. The portable method is to declare inputs, generators, seeds, environment and comparison rule, then report what is and is not identical.
Changed-context check: port the analysis from a laptop CPU to an approved GPU service. Keep the same data and seed plan, document the hardware change and test whether numerical differences alter the scientific conclusion.
Does setting one global seed solve reproducibility?
No. Libraries can use separate generators, and environment, data and parallel operations can still vary. Pass randomness explicitly where the API supports it.
Should every experiment use the same seed?
Use a fixed seed for a repeatability check. Use a predeclared set or sampling plan when studying sensitivity. The design should answer the research question.
What seed number is best?
There is no scientifically lucky seed. Choose and record it before interpreting the result.
Must results match exactly?
Not always. Define whether the artefact requires exact equality, numeric tolerance or stable scientific interpretation, and justify that rule.
Sources and next reading
- NUS Libraries — Research Data Management
- NumPy — Random Sampling
- scikit-learn — Common Pitfalls: Controlling Randomness
Continue inside eduKateSG
- University research environments and dependency lockfiles
- University research figures and reproducible charts
- University data-cleaning decision logs